Data Strategy and ROI for Generative AI and Knowledge Graphs, 2023
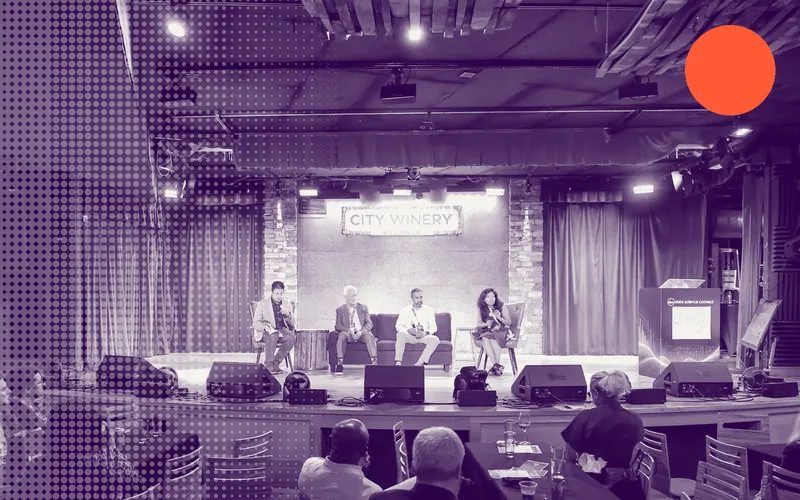
In a panel at the Data Science Innovators Conference 2023, data leaders from Kellogg, Travelers, ADP, Honeywell and Stardog discussed how to evaluate generative AI and knowledge graphs. They covered LLM privacy trade-offs, failure modes, ROI methods and governance.
By The AI Enterprise Magazine Team4 min read
Key takeaways
- Judge technology by results. Sirin advised looking at what a technology delivers to separate hype from reality.
- Define the failure mode. Zirnstein said each use case should be judged by what happens when the model is wrong.
- Weigh privacy early. Patel described the choice between sending proprietary data out and building smaller models behind the firewall.
- Estimate ROI bottom-up. Patel suggested valuing each use case, spreading shared costs and weighting by probability of success.
- Build the foundation. Li said data access, integration and privacy layers should not be neglected while chasing new technology.
At the Data Science Innovators Conference 2023, a panel of data science and architecture leaders from Kellogg Company, Travelers, ADP, Honeywell and Stardog took on a question every data team faced that year: how to keep up with generative AI and knowledge graphs without losing sight of return on investment. The session, "Top Data Initiatives for 2023: ROI and Data Strategy in the Face of Emerging Technologies Like Generative AI & Knowledge Graphs," was moderated by Mandy Sadowski, VP of Marketing at Stardog.
Panelists were Meet Patel, Senior Director, Global Advanced Analytics at Kellogg Company; Lina Li, Senior Director, Enterprise Architecture at Travelers; Melissa Ngamini, PhD, Lead Data Scientist at ADP; Jan Zirnstein, Director of Data Science at Honeywell; and Evren Sirin, CTO and co-founder of Stardog. Sadowski noted that the panelists spoke for themselves, not their employers.
How do data teams keep up with fast-moving technology?
Zirnstein described a three-part approach at Honeywell. His team stays involved in analytics communities and runs an internal journal club that reviews conference proceedings. It relies on strategic technology partners for infrastructure that is not a differentiator, and it works with a government relations function on pending data legislation. He cited the EU Data Act, which he said could force companies to expose derived data that often represents their intellectual property.
Sirin said the pressure is not new. The year before, he noted, the question had been data mesh versus data fabric. His advice was to "look at the results to kind of separate the hype from the reality," whether the technology is blockchain, large language models or knowledge graphs.
What should enterprises weigh before deploying large language models?
Patel walked through a hypothetical employee-support chatbot. Training a model on internal wikis and company data raises a privacy question: whether to push proprietary data to an outside service or build a smaller model behind the company firewall. He expected a "sweet spot" within months as options matured.
Ngamini said ADP's specialized vocabulary means off-the-shelf models often miss the point, so fine-tuning is attractive but hard to do efficiently at scale. Her suggestion was to pick a few domains, prove the approach there and carry the lessons to other use cases.
Zirnstein urged teams to define the failure mode of each use case. A wrong product recommendation and a wrong decision about a critical asset in a hospital carry very different costs.
Where do generative AI and knowledge graphs fit together?
Sirin pointed out that large language models are statistical, so users are not guaranteed the same answer twice. For financial customers working on operational risk or regulatory compliance, he said, "you cannot generate answers that are probably almost right but not right." He predicted more combining of statistical models with logical, explainable inference, an area he acknowledged Stardog has a stake in.
Zirnstein added that generative models suit tasks where a human reviews the output, such as marketing copy or code suggestions. Asking one to recall facts from a knowledge graph is different, he said: the answer will sound right, but that is not proof it is right.
Li reminded the group that AI attention has gone to unstructured data while structured data remains essential. Teams, she said, should "not forget to build this foundational layer" for data access, integration and privacy while chasing the newest technology.
How should teams measure ROI on data initiatives?
Patel favored a bottom-up method: estimate the value of each use case, such as EBIT or operating profit, then spread the cost of shared technology across projects. He suggested weighting expected value by the probability that a project succeeds, to get a directional ROI.
Zirnstein added cost savings, such as moving a workload from a relational store to a graph database, and productivity gains from automation, AutoML and removing barriers for data scientists. Sirin warned that maintenance costs over the years are easy to miss when comparing build against buy.
Ngamini measured return by whether the people using ADP's tools could work better, for instance shorter calls and faster chatbot answers. She said companies should consider the people affected by automation. Li suggested defining the value of a new capability creatively where no baseline exists, and noted that automation can free staff for other work.
What did the panel say about governance and starting out?
Asked whether data governance is maturing fast enough, Zirnstein said no, citing gaps in access controls, anonymization, explainability and bias detection. Another panelist said governance is an organizational culture issue, not one team's problem. Li advised starting with data dictionaries, metadata capture and lineage, and keeping architecture open and flexible because vendors and products change monthly.
Closing advice centered on curiosity with skepticism. Ngamini urged reading the research papers, and Zirnstein said "data is a team sport," encouraging practitioners to attend conferences and compare notes.
Where can you hear more from enterprise AI leaders?
The strategy questions in this 2023 discussion, including ROI, governance and build versus buy, continue on the stage at The AI Enterprise Conference 2027 on Tuesday, August 31, 2027, at Pier Sixty in New York City. Details are at /events/ai-enterprise-conference/. Registration for 2027 events is coming soon.
Frequently asked questions
How do you measure ROI on data initiatives?
Patel described estimating the value of each use case, allocating shared technology costs across projects and weighting by probability of success. Others added cost savings, productivity gains and maintenance costs.
Should companies send proprietary data to outside LLM services?
Panelists noted the privacy trade-off: pushing proprietary data to external services versus building smaller models behind the company firewall, with open source alternatives expected to draw attention.
Why combine knowledge graphs with generative AI?
Sirin said LLMs are statistical and can be almost right but not right, so use cases such as compliance benefit from logical, explainable inference.
Is data governance keeping pace with new AI?
Zirnstein said no, pointing to gaps in access, anonymization, explainability and bias detection.
This article is based on remarks by Mandy Sadowski, VP of Marketing, Stardog (moderator); Evren Sirin, CTO & Co-founder, Stardog; Meet Patel, Senior Director, Global Advanced Analytics, Kellogg Company; Lina Li, Senior Director, Enterprise Architecture, Travelers; Melissa Ngamini, PhD, Lead Data Scientist, ADP; Jan Zirnstein, Director Data Science, Honeywell at Data Science Innovators Conference 2023 on April 12, 2023. More coverage: More AI Connect Events.
Filed under: AI Strategy & ROI, Data & AI Infrastructure, AI Governance & Trust